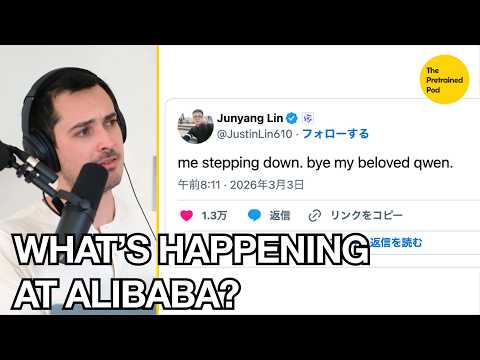
Pierce Freeman and Richard Diehl Martinez discuss reports that Junyang Lin and other Qwen researchers were leaving Alibaba. They acknowledge uncertainty about the situation and possible reorganization, contrasting the news with enthusiasm for the recently released Qwen3.5 family.
The episode explains why full attention becomes expensive as input length grows and why recurrent, linear-attention approaches can reduce some of that cost. The hosts use copying and associative recall as examples of information that compressed memory can struggle to retain.
Gated DeltaNet provides a way to update and gate a running memory state. Qwen3.5 combines that approach with full attention rather than relying on either alone, seeking a practical balance between efficiency and retrieval. These are architectural trade-offs, not proof that every linear-attention model is incapable of copying.
The hosts end with hopes for continued open-model development and competing interpretations of a reported follow-up message. Their expectations about future leadership, releases and licensing remain unresolved at the time of the episode; the discussion does not establish that the entire Qwen team quit.
 Watch on YouTube