Wes Roth explains DreamRSI as a way to improve the choice of research experiments rather than the experiments themselves. Recorded discovery trees provide a simulation of the search space already explored, allowing candidate exploration policies to be compared without rerunning every costly experiment.
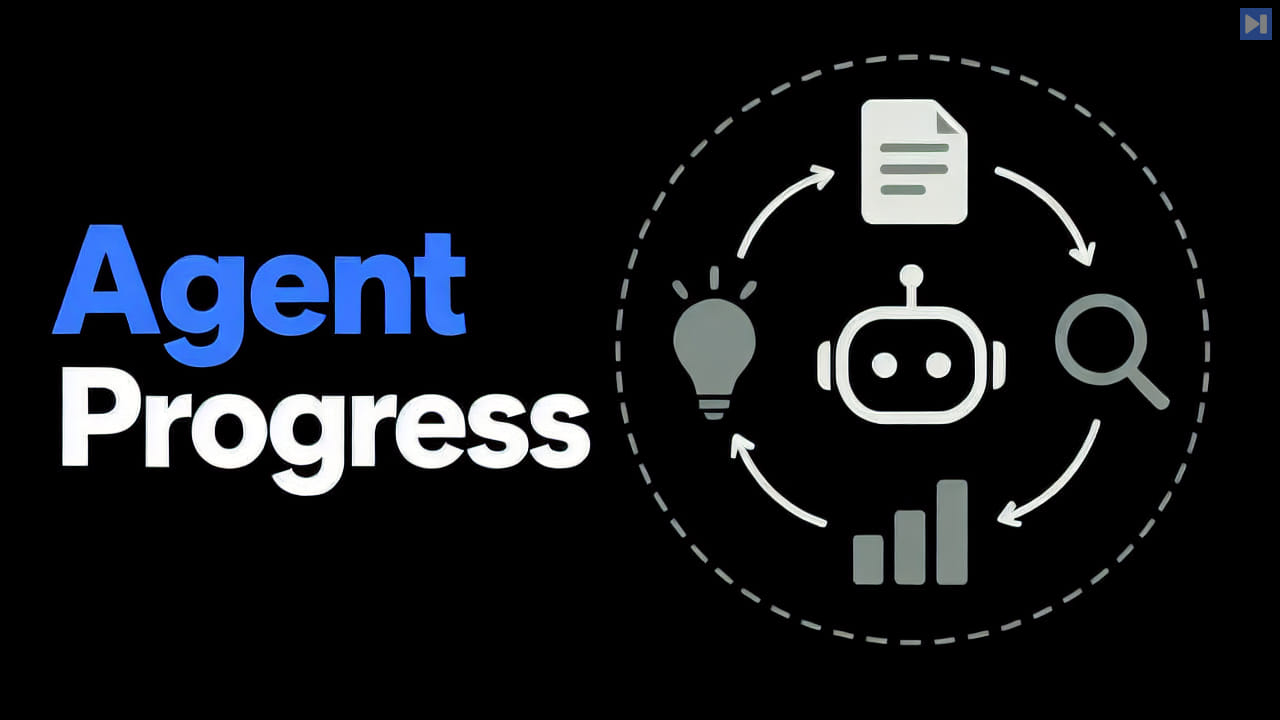
Wes Roth describes an iterative process in which the winning policy returns to live exploration and contributes a new discovery tree. A growing pool of histories can reduce dependence on the luck of a single run. The approach remains bounded by the experiments and search space represented in those histories.
Wes Roth compares this exploration-focused method with other AI-assisted research tools, including AlphaEvolve. The discussion connects experiment scheduling with broader self-improvement ambitions, but does not establish that simulated historical search alone produces unrestricted recursive improvement or general intelligence.
 Watch on YouTube