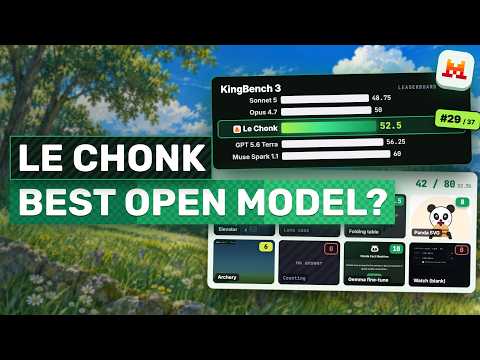
AICodeKing connects the Mistral Large 4 preview to OpenCode through OpenRouter and tests eight repeatable prompts in fresh folders. The review grades delivered artifacts rather than the agent's explanation, checking actual browser rendering and interaction. An elevator simulation, folding table and panda SVG work well, although smaller visual and interaction defects prevent perfect scores.
Other tasks expose reliability problems: the first contact-lens case and counting attempts produce no usable answer, the archery game has tiny targets and layout issues, and a 3D watch initially fails because of missing module paths. The presenter keeps separate repair attempts outside the main total, but counts a successful local Gemma fine-tuning rerun after correcting a permissions problem caused by the test setup.
The resulting first-pass score is 42 out of 80. The presenter treats that as evidence from one particular harness and prompt set, not a universal model ranking, and recommends keeping browser testing close when using the model for longer work.
 Watch on YouTube