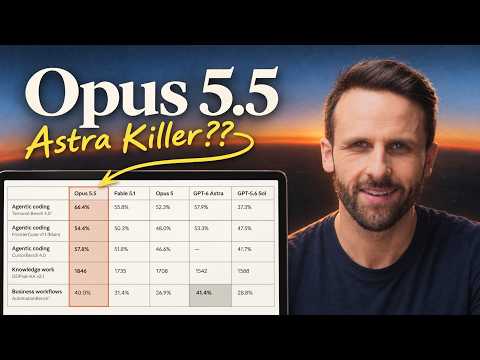
Pat Simmons reviews Anthropic's Opus 5.5 benchmarkA benchmark is a standardized task or collection of tests used to compare AI systems under defined conditions. and efficiency claims before testing the model against Fable 5.1 and GPT-6 Astra. He discusses token pricingToken pricing is the rate an AI provider charges for processing input tokens, generating output tokens, or reading cached tokens., task costsCost per completed task measures the total AI, tool, infrastructure, retry, and repair expense for each verified useful outcome. and reasoning effortReasoning effort is the amount of internal computational work an AI model applies before producing an answer or action., then uses blind rankings to compare generated websitesCode generation uses AI or another automated system to create source code from instructions, examples, schemas, or higher-level specifications., a browser game and a 3D product page.
Pat Simmons finds different winners across the four builds. Fable 5.1 leads his award-winning website recreation, while Opus 5.5 performs best in the product-brand recreation and Roller Coaster Tycoon-style game. GPT-6 Astra produces his preferred shoe model, although its integration into the surrounding website is less successful.
Pat Simmons highlights incomplete images, weak interface behavior, imperfect 3D details and uneven gameplay rather than treating every output as production-ready. He compares reported build costs and durations, while explicitly cautioning that four single-shot tests cannot establish general superiority or reliability on long-running engineering tasks.
 Watch on YouTube