Sofia Jakovcevic illustrates how a small prompt change can improve one measure while harming another. She uses a support-agent example to show why teams need to examine runtime behavior as well as the code diff.
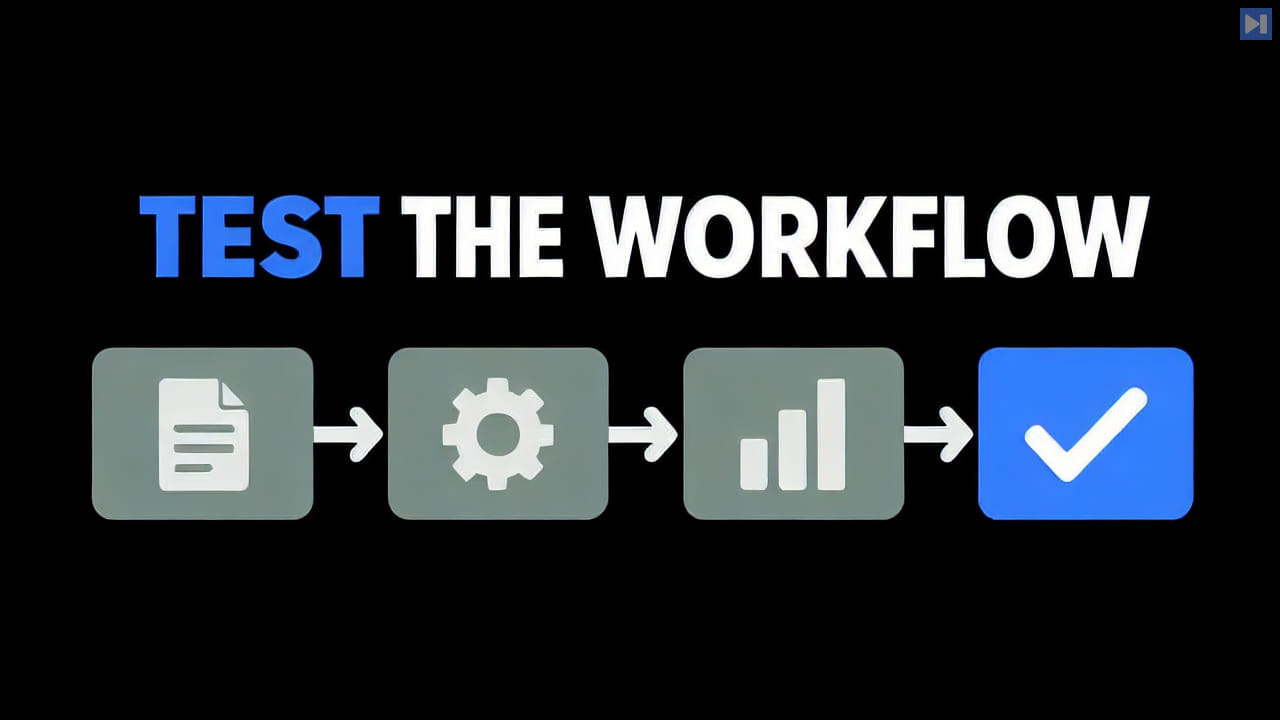
She outlines a regression loopAI regression testing reruns preserved cases to detect whether a model or agent update has broken behavior that previously worked.: select representative traces including failures and successful cases, score them with evaluatorsEvaluation is the systematic assessment of a system's behaviour or results against explicit criteria., compare changes with a baseline and apply agreed criteria in continuous integration. Her demonstration uses Arize tools to run experiments.
Jakovcevic discusses connecting coding agents with observability data so they can investigate failures and propose fixesAn AI feedback loop occurs when AI outputs or their consequences become inputs that influence later model or agent behavior.. She presents this as a direction for faster iteration rather than evidence that automated fixes are always safe or correct.
 Watch on YouTube