Theo Browne examines changes to coding-assistant subscriptions and distinguishes subscription allowances, nominal API value and the cost of completing a taskCost per completed task measures the total AI, tool, infrastructure, retry, and repair expense for each verified useful outcome.. Theo Browne's usage comparisons suggest that a cheaper model can preserve practical capacity even when an allowance appears smaller in dollar terms.
Theo Browne compares model choicesModel selection chooses the AI model whose capability, quality, cost, speed, safety, and operating constraints best fit a task. using personal usage measurements and task benchmarksA benchmark is a standardized task or collection of tests used to compare AI systems under defined conditions., while acknowledging a preference for another coding model for some engineering work. Assertions about provider margins and intended pricing are Theo Browne's hypotheses, not verified company finances.
Theo Browne criticizes the timing and communication of plan changes and describes fast-mode usage consuming his limits quickly. The concluding workflow uses different models for building and review, emphasizing results and workload fit rather than treating a higher-priced plan as an automatic improvement.
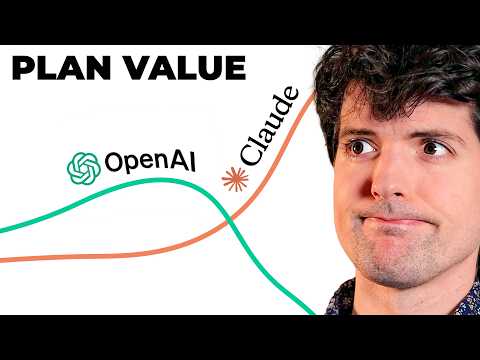 Watch on YouTube