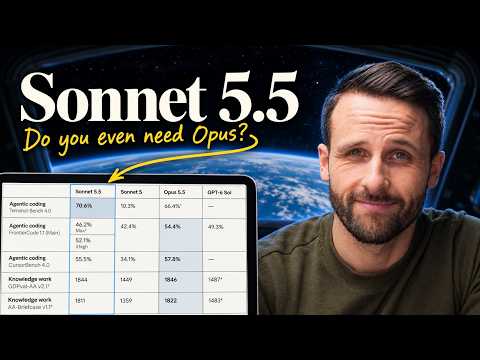
Pat Simmons compares Sonnet 5.5 with Opus 5.5, Fable 5.1, GPT-6 Astra and Sonnet 5 using shared prompts, tools and high reasoning effort. He reviews published benchmarks before conducting blind rankingsBlind AI model evaluation compares model outputs while hiding model identity so expectations and brand knowledge are less likely to influence judgments. of a product launch video, a complex website recreation and a browser horror game.
Sonnet 5.5 finishes third in the launch-video and website comparisons, while placing second in the horror-game test. Opus produces his preferred launch video; website quality depends on whether he emphasizes 3D assets or the rest of the interface, and Fable wins the horror game's atmosphere.
The reported costs vary sharply with how long each agent works. Sonnet's website attempt runs much longer than the alternatives and costs more than Opus or Fable, illustrating why a lower token price does not necessarily mean a cheaper completed taskCost per completed task measures the total AI, tool, infrastructure, retry, and repair expense for each verified useful outcome..
Pat Simmons recommends Sonnet for routine work and selected editing tasks, with stronger models checking larger builds. These are limited, qualitative comparisons using his own skills and tools, not proof of a universal ranking or guaranteed savings.
 Watch on YouTube