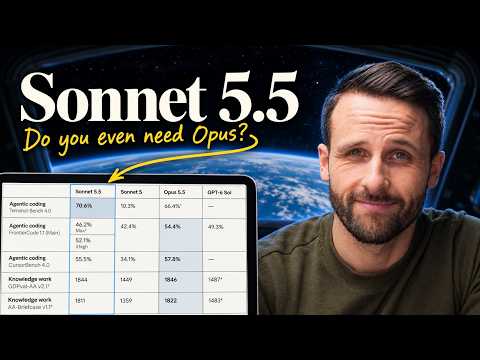
Pat Simmons compares Sonnet 5.5 with Opus 5.5, Fable 5.1, GPT-6 Astra and Sonnet 5 using shared prompts, tools and high reasoning effortA benchmark is a defined test or collection of tasks used to compare a system's performance under specified conditions.. He reviews published benchmarks before conducting blind rankingsEvaluation is the systematic assessment of a system's behaviour or results against explicit criteria. of a product launch video, a complex website recreation and a browser horror game.
Sonnet 5.5 finishes third in the launch-video and website comparisons, while placing second in the horror-game test. Opus produces his preferred launch video; website quality depends on whether he emphasizes 3D assets or the rest of the interfaceHuman judgment in AI is the accountable interpretation and decision-making people contribute when setting goals, evaluating evidence, and managing consequences., and Fable wins the horror game's atmosphere.
The reported costs vary sharply with how long each agent works. Sonnet's website attempt runs much longer than the alternatives and costs more than Opus or Fable, illustrating why a lower token price does not necessarily mean a cheaper completed taskCost per completed task measures the total AI, tool, infrastructure, retry, and repair expense for each verified useful outcome..
Pat Simmons recommends Sonnet for routine work and selected editing tasks, with stronger models checking larger builds. These are limited, qualitative comparisons using his own skills and tools, not proof of a universal ranking or guaranteed savings.
 Watch on YouTube